TESTED · PDF WORKFLOWS
Make a scanned PDF searchable, then catch the OCR mistakes
Make scanned PDFs searchable and check OCR errors with actual receipt examples, original scans, processed PDFs, and extracted text you can download.
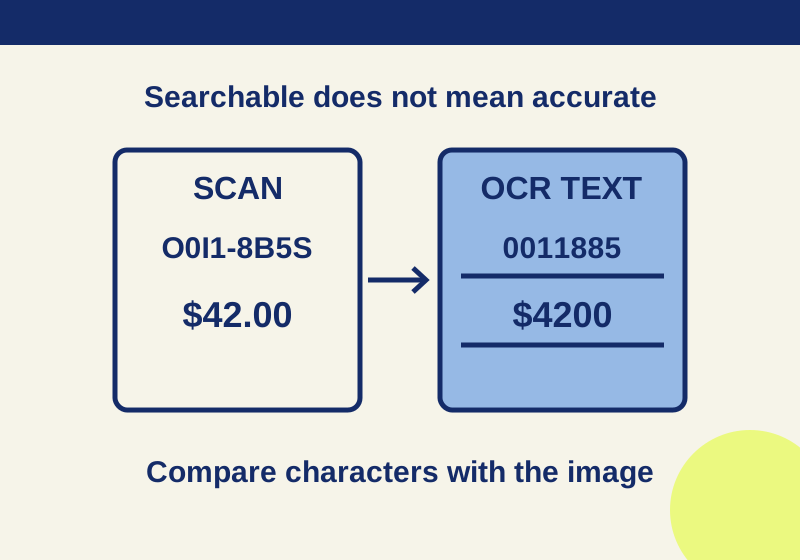
To find a receipt number in a scanned PDF, first check whether the file already contains searchable text. Open it and search for a phrase you can see on the page. If search finds nothing and you cannot select the words, the page may be an image that needs optical character recognition, or OCR.
OCR can add a text layer so you can search and copy words while keeping the scanned page visible. A successful search does not prove that every copied character is right. In a one-page practice receipt, OCR found the total in both a clear scan and a deliberately degraded one, but misread a part code and a labor charge in the degraded version.
Add searchable text
If the PDF already has selectable text, use that text rather than running OCR automatically. For an image-only file, save a backup before processing it.
Adobe’s Acrobat instructions use All tools > Scan & OCR > In this file. Choose the page range and language, then select Recognize Text. Adobe says this adds a searchable text layer and advises reviewing its accuracy and completeness.
For a long PDF, confirm the page count and the range you selected before processing. Afterward, search for a visible phrase on an early page and another on a late page. If a page is truly blank, finding no words there is expected.
What changed in the practice receipt
The test used a synthetic, one-page US-letter receipt with no real customer data. The same text was rasterized as a clear 300 dpi image and as a deliberately degraded 60 dpi image with added blur. Both image-only PDFs had no extractable text before OCR. The clear image’s recognized text matched every nonblank line of the original. The degraded image produced these results:
| Receipt field | Original text | Degraded image’s OCR |
|---|---|---|
| Receipt number | RV-1048 |
RV-1048 |
| Date | 2026-10-07 |
2026-1007 |
| Part code | O0I1-8B5S |
0011885 |
| Service labor | $42.00 |
$4200 |
| Tax | $4.87 |
487 |
| Total paid | $65.77 |
$65.77 |
The total survived, so checking only $65.77 would have missed the errors. In the resulting searchable PDFs, a search for RV-1048 and $65.77 found one match in each. The exact part code and $42.00 were found in the clear version and had no matches in the degraded version. The page images remained visually unchanged in each before-and-after pair: the mistakes were in the added text.
Try the before-and-after files
These downloads contain the synthetic receipt. Open each original PDF and search for RV-1048; then repeat the search in its searchable counterpart.
- Clear input: image-only PDF and searchable PDF
- Degraded input: image-only PDF and searchable PDF
- To check copied text: original answer key and text extracted from the degraded searchable PDF
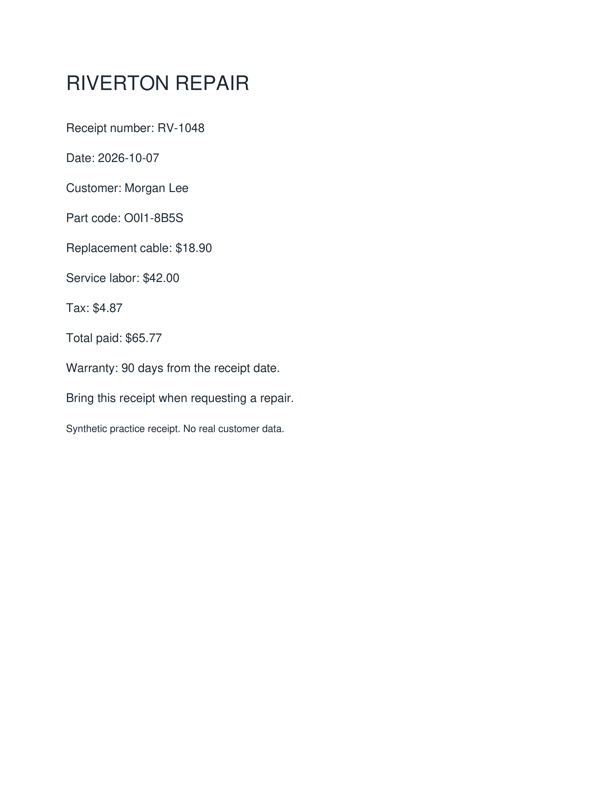
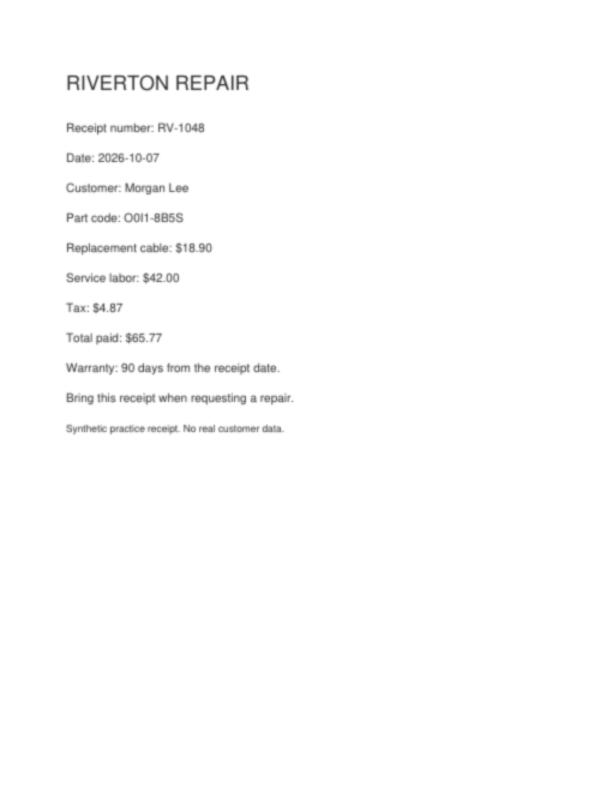
In the searchable files, try the exact part code O0I1-8B5S, then copy the labor charge and compare it with the visible receipt and answer key. The first two characters of the code are the letter O and the number zero; the next two are a capital I and the number one. Replacing them with an all-numeric guess changes the identifier. The poor scan also lost the hyphen and other characters, so checking only whether the code has a similar length would miss the problem.
To see the errors without a PDF viewer’s selection behavior, open the clear image’s recognized text and poor image’s recognized text. These are the OCR results before the PDF text layer was added. The downloadable extracted text comes from reopening the finished PDF. Comparing both stages helps locate an error: a wrong word already present in the recognition result needs a recognition correction; trouble introduced while copying from a particular viewer calls for checking its handling of the text layer.
The receipt amounts also give you a short cross-check: $18.90 + $42.00 + $4.87 = $65.77. The blurry OCR kept the final total while dropping punctuation in the labor and tax lines. A total that agrees with the scan therefore cannot validate every line item. Compare the individual fields you intend to record, including their labels, before importing them as numbers.
Review the values you will use
For a receipt, check the amount, decimal point, date, quantity, and any reference or part code against the visible page before putting them into an expense record. For a contract or research scan, search for an exact value together with its nearby label so a match elsewhere in the document does not stand in for the passage you need.
If you need more than isolated values, copy a paragraph and check its reading order, especially when the page has columns. Keep the page image available for comparison: adding searchable text does not, by itself, establish that a PDF has a fully editable layout or complete document accessibility.
Adobe’s correction workflow is under All tools > Scan & OCR > Correct recognized text. Select Review recognized text to display boxes around uncertain words. Select a box, edit Recognized as, and choose Accept to move to the next item. Compare other values you will use with the image too; the suspect review gives you places to inspect, without establishing that every unboxed value is correct.
If search works but the text is wrong
Compare the copied characters with the scan. If the source image is poor, use a better original scan when available and run OCR again. The practice test shows a difference between its clear and degraded inputs; it does not establish that enlarging an already degraded image restores lost detail.
For Tesseract specifically, its image-quality guidance recommends 300 dpi, notes that skew can impair text segmentation, and says a very small crop may need a whitespace border. It also notes that tables need custom layout analysis. Treat those as tool-specific guidance, not a promise that any scan at 300 dpi will be accurate.
If the page is readable but search finds nothing, check whether you opened the original image-only PDF, whether the intended page was included in the OCR range, and whether the chosen language matches the document. Then try both a visible phrase and a clear identifier. For a confidential document, use a processing method approved for that material before uploading it to any service solely for OCR.
The receipt examples were processed locally as PNG images with Tesseract.js 7.0.0 in English, using its single-uniform-block setting. PyMuPDF added the recognized words as invisible text over the original image. Tesseract.js itself does not read PDF input. The Acrobat steps are official documented instructions; this test covered one synthetic printed receipt, not Acrobat output, handwriting, multiple languages, photographed screens, or multipage documents.
KEEP GOING
More to explore.
TESTEDPDF workflows
Merge PDFs in the right order and catch missing pages
A three-page output can still be wrong. Practice merging two PDFs, then catch a reversed packet and a missing page hidden by a duplicate.
SOURCE-CHECKEDBusiness documents
Acrobat Standard vs Pro: when the extra $5 is worth paying
A real PDF covering-versus-removal example, current US prices and calculated costs for individual and team licenses.